Collection of miscellaneous R functions of interest only to Paul
This package provides tools for epidemiological visualisation, data simulation, and an interactive Shiny app for building SQL queries for Amazon Redshift.
Documentation: https://prcleary.github.io/paulmisc/
Installation
System Dependencies (Linux)
On Linux, you may need to install system libraries required by ggplot2 and other dependencies:
Debian/Ubuntu:
sudo apt-get install -y \
  libcurl4-openssl-dev \
  libssl-dev \
  libxml2-dev \
  libfontconfig1-dev \
  libharfbuzz-dev \
  libfribidi-dev \
  libfreetype6-dev \
  libpng-dev \
  libtiff5-dev \
  libjpeg-dev
RHEL/Fedora/Rocky Linux:
Features
Epidemiological Tools
-
geom_epicurve()- A flexible ggplot2 geom for creating classical epidemic curves where each case is represented as a small square. Features include:- Time period flexibility: Automatically handles hourly, daily, weekly, or monthly data
- Automatic column charts: Switches to column chart mode for large outbreaks (configurable threshold)
- Custom symbols: Use Unicode symbols or emoji instead of squares
- Full ggplot2 integration: Works with all scales, themes, facets, and aesthetics
- Interactive plotly support: Convert to interactive plots with custom tooltips
-
annotate_event()- Add vertical lines to mark specific events (e.g., interventions, exposures) -
annotate_period()- Shade time periods (e.g., exposure windows, investigation phases) -
simulate_outbreak()- Generate realistic outbreak data with configurable incubation periods
Shiny Applications
-
run_redshift_query_builder()- Interactive Shiny app for building Amazon Redshift SQL queries without writing code. Features include:- Form-based query construction
- Support for WHERE conditions, date filters, aggregates, GROUP BY, ORDER BY
- Real-time validation and error checking
- One-click copy to clipboard
- Dark-themed, modern UI
Usage
Basic Epidemic Curve
Create a simple epidemic curve from simulated outbreak data:
# Simulate a point-source outbreak
cases <- simulate_outbreak(n = 50, seed = 42)

# Create basic epicurve
ggplot(cases, aes(x = onset_date)) +
  geom_epicurve(fill = "steelblue") +
  labs(
    title = "Outbreak Epicurve",
    x = "Date of Onset",
    y = "Number of Cases"
  ) +
  scale_y_epicurve() +
  theme_minimal()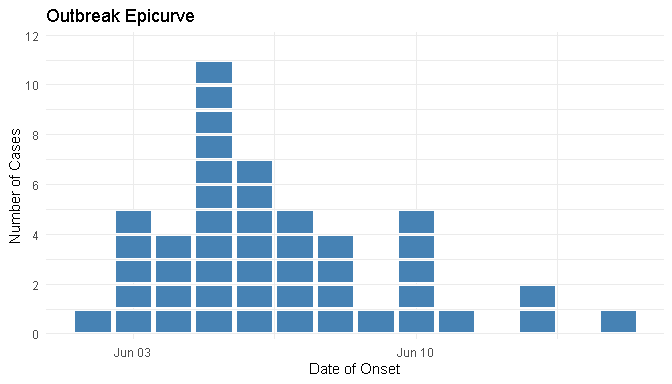
Coloured by Category
Visualise cases by demographic or clinical characteristics:
# Colour by age group
ggplot(cases, aes(x = onset_date, fill = age_group)) +
  geom_epicurve(colour = "grey20") +
  scale_fill_brewer(palette = "Set2") +
  labs(
    title = "Cases by Age Group",
    x = "Date of Onset",
    y = "Number of Cases",
    fill = "Age Group"
  ) +
  theme_bw()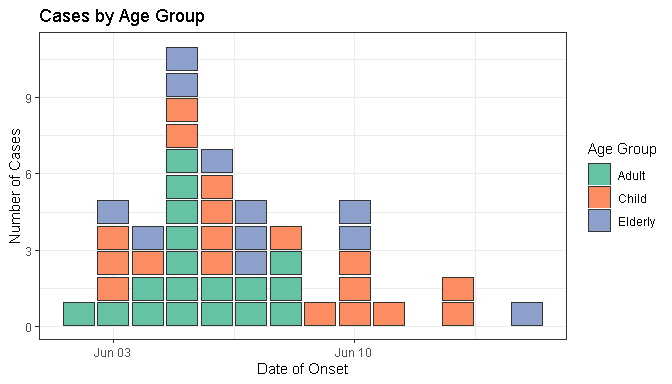
Faceted Analysis
Compare outbreaks across different settings or groups:
# Facet by setting and colour by outcome. Use the default `scales =
# "fixed"` so every case square has the same visual size across panels
# — with `scales = "free_y"` a sparse panel renders fewer cases as
# disproportionately tall blocks.
ggplot(cases, aes(x = onset_date, fill = outcome)) +
  geom_epicurve(height = 0.85) +
  facet_wrap(~ setting, ncol = 1) +
  scale_fill_manual(
    values = c("Recovered" = "steelblue", "Hospitalised" = "tomato")
  ) +
  labs(
    title = "Outbreak Comparison by Setting",
    x = "Date of Onset",
    y = "Number of Cases",
    fill = "Outcome"
  ) +
  scale_y_epicurve() +
  theme_minimal()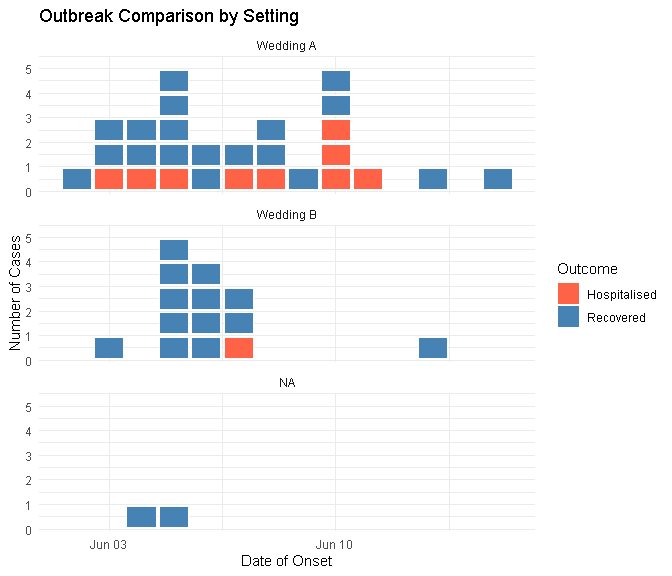
Custom Incubation Periods
Simulate outbreaks with different epidemiological characteristics by adjusting the incubation period parameters. The meanlog parameter controls the median incubation period (median = exp(meanlog) days), while sdlog controls the spread around that median:
# Short incubation period (e.g., Salmonella, norovirus)
# Median incubation: exp(0.5) ≈ 1.6 days
short_incubation <- simulate_outbreak(
  n = 100,
  exposure = as.Date("2024-08-15"),
  meanlog = 0.5,
  sdlog = 0.3,
  seed = 123
)

# Long incubation period (e.g., Hepatitis A)
# Median incubation: exp(3) ≈ 20 days
long_incubation <- simulate_outbreak(
  n = 100,
  exposure = as.Date("2024-08-15"),
  meanlog = 3,
  sdlog = 0.5,
  seed = 123
)

# Compare side by side
library(patchwork)

p1 <- ggplot(short_incubation, aes(x = onset_date)) +
  geom_epicurve(fill = "coral") +
  labs(title = "Short Incubation", x = NULL, y = "Cases") +
  scale_y_epicurve() +
  theme_minimal()

p2 <- ggplot(long_incubation, aes(x = onset_date)) +
  geom_epicurve(fill = "skyblue") +
  labs(title = "Long Incubation", x = "Date of Onset", y = "Cases") +
  scale_y_epicurve() +
  theme_minimal()

p1 / p2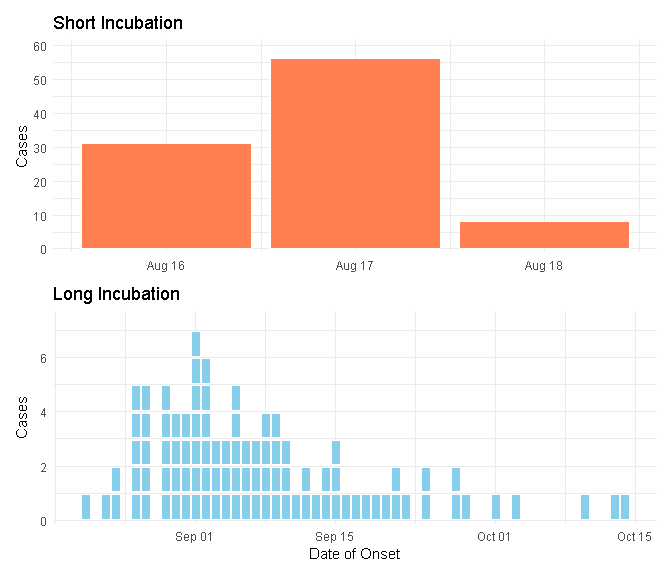
Different Time Periods
Epidemic curves automatically adapt to hourly, daily, weekly, or monthly data:
# Hourly data for rapid outbreak investigation. With sub-daily
# timestamps the auto-detected width is one hour; we use
# `scale_x_datetime()` so the x-axis labels hours-of-day rather than
# whole dates.
hourly_cases <- simulate_outbreak(
  n = 40,
  time_unit = "hourly",
  pattern = "continuous",
  date_range = 2,
  exposure = "2024-06-01",
  seed = 123,
  prop_missing = 0
)

p1 <- ggplot(hourly_cases, aes(x = onset_time)) +
  geom_epicurve(fill = "darkred") +
  scale_x_datetime(date_breaks = "6 hours",
                   date_labels = "%H:%M\n%d %b") +
  labs(title = "Hourly Epidemic Curve", x = "Time", y = "Cases") +
  scale_y_epicurve() +
  theme_minimal()

# Weekly aggregated data for surveillance — 21 weeks of continuous
# transmission gives a realistically long surveillance window.
weekly_cases <- simulate_outbreak(
  n = 120,
  time_unit = "weekly",
  pattern = "continuous",
  date_range = 21 * 7,
  exposure = "2024-01-01",
  seed = 456,
  prop_missing = 0
)

p2 <- ggplot(weekly_cases, aes(x = onset_date)) +
  geom_epicurve(fill = "forestgreen") +
  labs(title = "Weekly Epidemic Curve (21 weeks)",
       x = "Week", y = "Cases") +
  scale_y_epicurve() +
  theme_minimal()

p1 / p2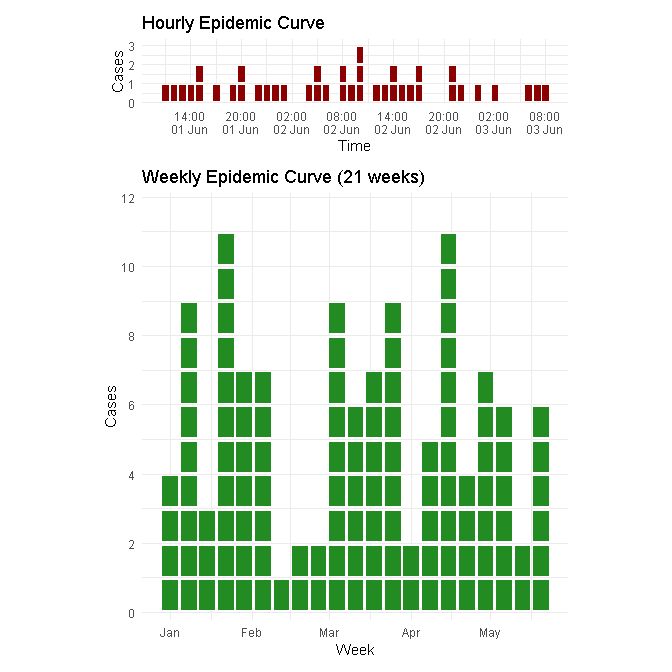
The width parameter automatically adjusts based on the time unit detected.
Automatic Column Charts for Large Outbreaks
When case counts exceed a threshold (default 20), the plot automatically switches to a column chart for better readability:
# Simulate a large continuous outbreak. With ~40 cases per day the auto-
# switch kicks in and the plot renders as a stacked column chart instead
# of individual squares.
large_outbreak <- simulate_outbreak(
  n = 600,
  pattern = "continuous",
  date_range = 14,
  exposure = "2024-01-01",
  seed = 789,
  prop_missing = 0
)

ggplot(large_outbreak, aes(x = onset_date, fill = age_group)) +
  geom_epicurve(max_stack = 20) +
  scale_fill_brewer(palette = "Set2", name = "Age group",
                    na.translate = FALSE) +
  labs(
    title = "Large Outbreak (Auto-switched to Column Chart)",
    subtitle = "Bars show daily case counts coloured by age group",
    x = "Date of Onset",
    y = "Number of Cases"
  ) +
  scale_y_epicurve() +
  theme_minimal()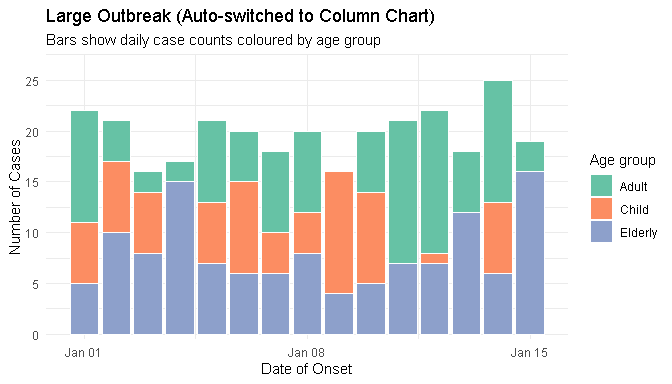
Control the threshold with max_stack parameter, or set max_stack = NULL to always show individual case squares.
Annotating Outbreak Timelines
Add context to epidemic curves with event markers and period shading:
# Create an outbreak timeline
outbreak_cases <- simulate_outbreak(n = 60, seed = 789)

ggplot(outbreak_cases, aes(x = onset_date)) +
  geom_epicurve(fill = "steelblue", alpha = 0.8) +
  # Shade the likely exposure period
  annotate_period(
    date = as.Date("2024-05-28"),
    end_date = as.Date("2024-06-02"),
    label = "Likely exposure period",
    fill = "yellow",
    alpha = 0.25
  ) +
  # Mark when investigation started
  annotate_event(
    date = as.Date("2024-06-03"),
    label = "Investigation\ninitiated",
    colour = "darkgreen"
  ) +
  # Mark when source was identified
  annotate_event(
    date = as.Date("2024-06-07"),
    label = "Source\nidentified",
    colour = "red"
  ) +
  labs(
    title = "Outbreak Timeline with Key Events",
    x = "Date of Onset",
    y = "Number of Cases"
  ) +
  scale_y_epicurve() +
  theme_minimal()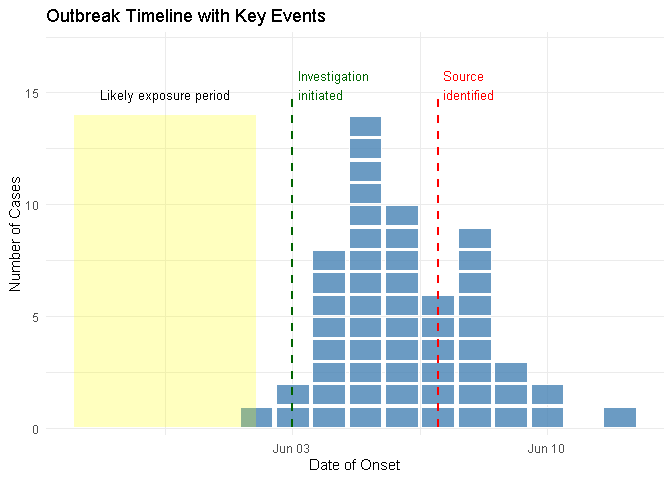
For interactive plotly timelines, see the interactive epicurves vignette which shows how to combine ggplot2 layers with plotly annotations.
Custom Symbols and Emoji
Replace squares with Unicode symbols or emoji for creative visualisations. When you pass a named vector to symbol, each category gets its own symbol and the legend is updated automatically — no guides(... override.aes = ...) boilerplate needed:
symbol_cases <- simulate_outbreak(n = 35, seed = 999, prop_missing = 0)

sex_symbols <- c(Female = "\u2640", Male = "\u2642")  # ♀ ♂
p1 <- ggplot(symbol_cases, aes(x = onset_date, colour = sex)) +
  geom_epicurve(symbol = sex_symbols, symbol_size = 6) +
  scale_colour_manual(values = c("Female" = "#D55E00", "Male" = "#0072B2")) +
  labs(title = "Different symbol per sex (\u2640 / \u2642)",
       x = NULL, y = "Cases") +
  scale_y_epicurve() +
  theme_minimal()

outcome_symbols <- c(Recovered = "\u25CB", Hospitalised = "\u2716")  # ○ ✖
p2 <- ggplot(symbol_cases, aes(x = onset_date, colour = outcome)) +
  geom_epicurve(symbol = outcome_symbols, symbol_size = 6) +
  scale_colour_manual(
    values = c("Recovered" = "steelblue", "Hospitalised" = "tomato")
  ) +
  labs(title = "Different symbol per outcome (\u25CB / \u2716)",
       x = "Date of Onset", y = "Cases") +
  scale_y_epicurve() +
  theme_minimal()

p1 / p2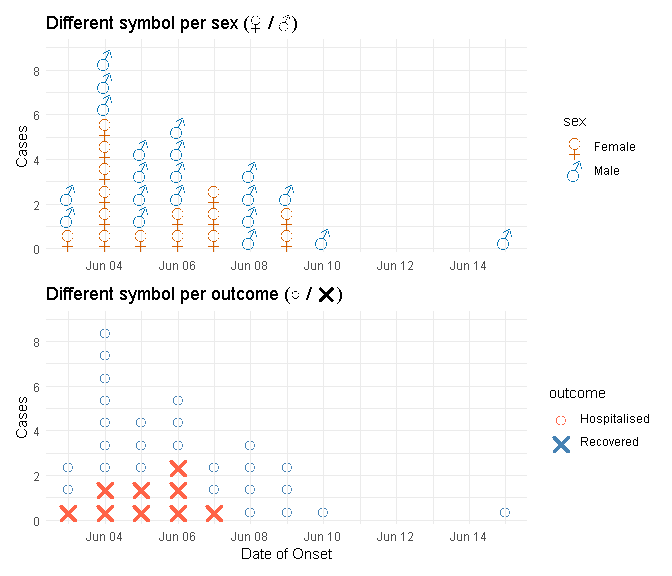
Emoji and other Unicode glyphs work too. Rendering depends on the graphics device’s font support; the example below uses widely-supported geometric shapes so the per-category mapping is unambiguous:
age_symbols <- c(Child = "\u25B2",   # ▲ triangle
                 Adult = "\u25CF",   # ● circle
                 Elderly = "\u25A0") # ■ square
ggplot(cases, aes(x = onset_date, colour = age_group)) +
  geom_epicurve(symbol = age_symbols, symbol_size = 6) +
  scale_colour_manual(values = c(Child = "#D55E00", Adult = "#0072B2",
                                 Elderly = "#009E73")) +
  labs(title = "Cases by age group (one symbol per category)",
       x = "Date", y = "Cases") +
  scale_y_epicurve() +
  theme_minimal()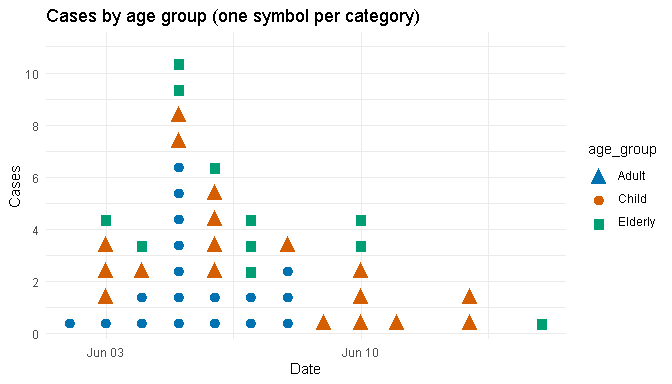
Integer y-axis with scale_y_epicurve()
Case counts are integers by definition, so a y-axis showing values like 2.5 or 7.5 is misleading. scale_y_epicurve() is a thin wrapper around ggplot2::scale_y_continuous() that:
- forces axis breaks to non-negative integers;
- uses
pretty()to pick visually sensible intervals; - accepts any other
scale_y_continuous()argument (limits,name,expand, …).
ggplot(cases, aes(x = onset_date)) +
  geom_epicurve(fill = "steelblue") +
  scale_y_epicurve(name = "Number of cases", limits = c(0, NA)) +
  theme_minimal()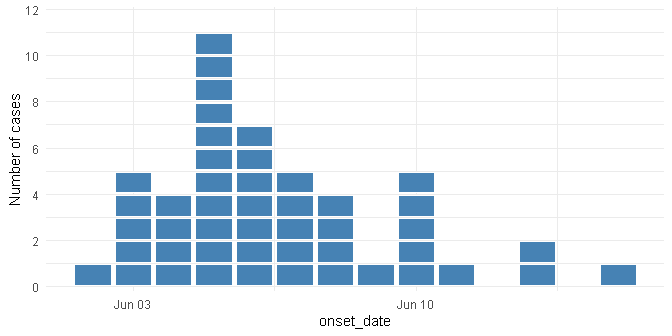
If you want fractional ticks (e.g. to compare against a rate), use the standard scale_y_continuous() instead.
Automatic footnotes with epicurve_footnote()
Every real outbreak plot should disclose when it was generated and how much information is missing. epicurve_footnote(data) returns a labs(caption = ...) element that summarises the proportion of rows with at least one missing value and stamps the chart with the current date and time. Add it to any plot with +:
ggplot(cases, aes(x = onset_date, fill = age_group)) +
  geom_epicurve() +
  scale_fill_brewer(palette = "Set2") +
  labs(title = "Cases with auto-footnote", x = NULL, y = "Cases") +
  scale_y_epicurve() +
  theme_minimal() +
  epicurve_footnote(cases)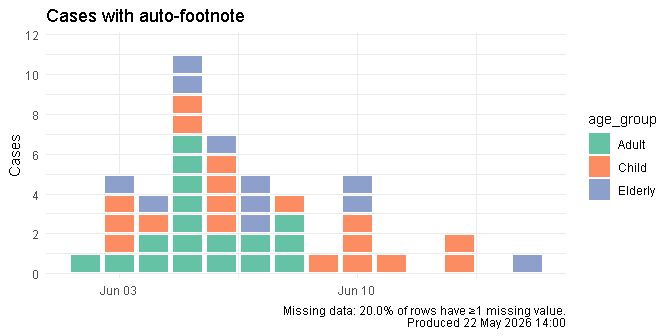
Realistic line list with missing data
simulate_outbreak() injects a small proportion of missing values into the demographic and onset columns by default, mirroring what real notification systems look like. You can tune the level with prop_missing:
realistic <- simulate_outbreak(n = 120, seed = 2024, prop_missing = 0.08)

ggplot(realistic, aes(x = onset_date, fill = outcome)) +
  geom_epicurve() +
  scale_fill_manual(values = c(Recovered = "steelblue",
                               Hospitalised = "tomato")) +
  labs(title = "Outbreak with realistic missingness",
       x = "Date of onset", y = "Cases",
       fill = "Outcome") +
  scale_y_epicurve() +
  theme_minimal() +
  epicurve_footnote(realistic)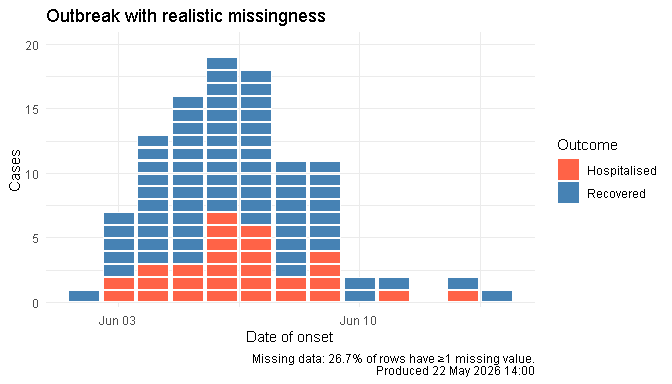
A complex, realistic example
This example pulls in nearly every feature of the package: missing data, faceting, custom symbols per category, an automatic footnote, an exposure-window shading, and an event line marking when control measures began.
outbreak <- simulate_outbreak(
  n = 180,
  exposure = as.Date("2024-04-22"),
  meanlog = 1.4,
  sdlog = 0.55,
  prop_missing = 0.04,
  seed = 7
)

sex_symbols <- c(Female = "\u2640", Male = "\u2642")

# Drop rows with NA in the aesthetics we use (real-life chart prep)
plot_data <- outbreak[!is.na(outbreak$sex) &
                        !is.na(outbreak$setting) &
                        !is.na(outbreak$onset_date), ]

ggplot(plot_data, aes(x = onset_date, colour = sex)) +
  geom_epicurve(symbol = sex_symbols, symbol_size = 4) +
  annotate_period(
    date = as.Date("2024-04-22"),
    end_date = as.Date("2024-04-26"),
    label = "Suspected exposure window",
    fill = "gold", alpha = 0.25
  ) +
  annotate_event(
    date = as.Date("2024-05-02"),
    label = "Control\nmeasures begin",
    colour = "darkgreen"
  ) +
  scale_colour_manual(
    values = c(Female = "#D55E00", Male = "#0072B2"),
    name = "Sex"
  ) +
  # Use the default fixed y-axis across panels so symbols remain the
  # same visual size in every setting — `scales = "free_y"` would
  # rescale each panel and visually stretch symbols in sparse panels.
  facet_wrap(~ setting, ncol = 1) +
  labs(
    title = "Multi-setting outbreak with missing data",
    subtitle = "Symbols per sex, exposure shaded, intervention marked",
    x = "Date of onset", y = "Cases"
  ) +
  scale_y_epicurve(expand = ggplot2::expansion(mult = c(0, 0.25))) +
  theme_minimal() +
  epicurve_footnote(outbreak)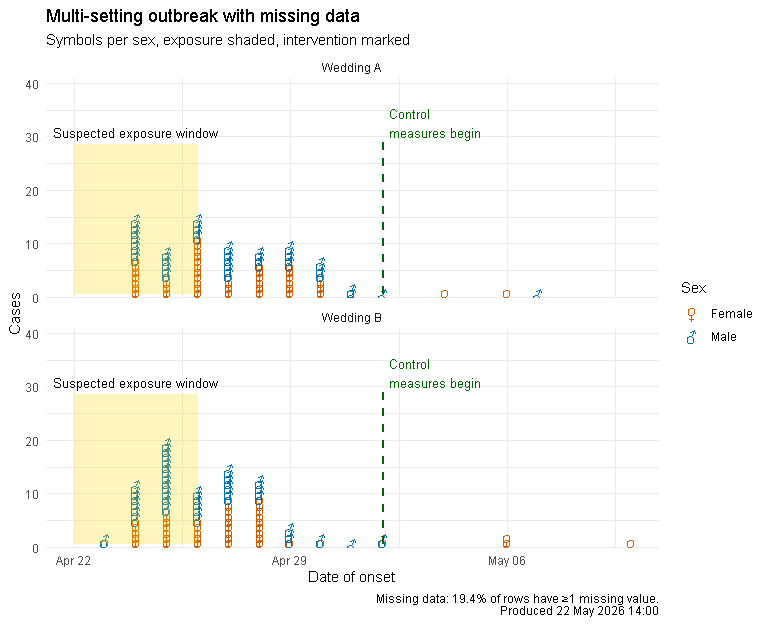
Advanced Customisation
Fine-tune the appearance of individual case squares:
# Adjust spacing and size
ggplot(cases, aes(x = onset_date, fill = sex)) +
  geom_epicurve(
    width = 0.8,   # Horizontal spacing (0-1)
    height = 0.95, # Vertical spacing (0-1, higher = less gap)
    colour = "white",
    linewidth = 0.2
  ) +
  scale_fill_manual(values = c("Male" = "#0072B2", "Female" = "#D55E00")) +
  labs(
    title = "Cases by Sex with Custom Styling",
    x = "Date of Onset",
    y = "Number of Cases"
  ) +
  scale_y_epicurve() +
  theme_minimal()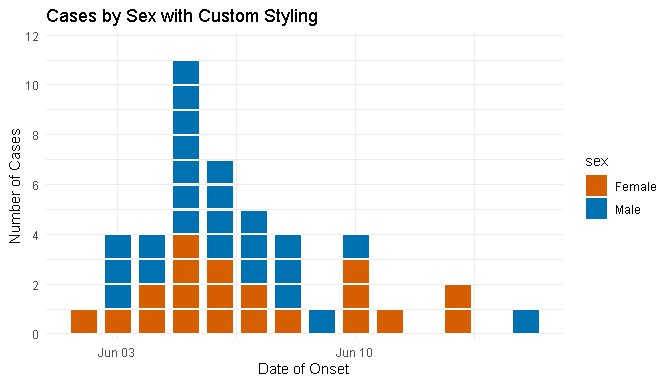
Interactive Plotly Visualisation
Create interactive epidemic curves with custom tooltips using plotly::ggplotly():
library(plotly)

# Add custom tooltip text to the data
cases$tooltip <- paste0(
  "Case ID: ", cases$case_id, "<br>",
  "Date: ", cases$onset_date, "<br>",
  "Age: ", cases$age_group, "<br>",
  "Sex: ", cases$sex, "<br>",
  "Setting: ", cases$setting
)

# Create plot with text aesthetic for tooltips
p <- ggplot(cases, aes(x = onset_date, fill = age_group, text = tooltip)) +
  geom_epicurve() +
  scale_fill_brewer(palette = "Set2") +
  labs(
    title = "Interactive Epidemic Curve",
    x = "Date of Onset",
    y = "Number of Cases"
  ) +
  theme_minimal()

# Convert to interactive plotly plot
ggplotly(p, tooltip = "text")
Users can hover over individual case squares to see detailed information.
See the Interactive Epidemic Curves with Plotly article for live interactive examples you can try in your browser!
Redshift SQL Query Builder
Launch the interactive Shiny app for building SQL queries:
# Launch the Redshift SQL Query Builder Shiny app
run_redshift_query_builder()
The app provides a user-friendly interface for:
- Table Selection: Specify schema, table name, and optional alias
- Column Selection: Choose all columns, specific columns with DISTINCT, or aggregate functions (COUNT, SUM, AVG, MIN, MAX, COUNT DISTINCT)
- WHERE Conditions: Add up to 3 conditions with AND/OR logic using various operators (=, !=, >, <, >=, <=, LIKE, ILIKE, IN, NOT IN, IS NULL, IS NOT NULL, BETWEEN)
- Date Filters: Filter by date ranges, last N days, current month/year, or specific dates using Redshift-specific functions like DATEADD and TRUNC
- Sorting & Grouping: GROUP BY, HAVING, ORDER BY with LIMIT and OFFSET
- Validation: Real-time error checking with helpful validation messages
- Copy to Clipboard: One-click copy of the generated SQL query
The app features a modern dark theme and includes helpful Redshift SQL tips for common functions and patterns.
Development
Setup
Clone the repository and install development dependencies:
# Install development packages
install.packages(c("devtools", "testthat", "roxygen2", "pkgdown"))

# Load the package
library(paulmisc)
Testing
Run the test suite to ensure everything works correctly:
# Run all tests
devtools::test()

# Run tests with coverage report
covr::package_coverage()
Documentation
Update documentation after modifying roxygen comments:
# Generate documentation from roxygen comments
devtools::document()

# Preview documentation for a function
?geom_epicurve
Package Checks
Run R CMD check to ensure the package meets CRAN standards:
# Run comprehensive package checks
devtools::check()

# Check for common issues
goodpractice::gp()Website
This package uses pkgdown for documentation website generation:
# Build the website
pkgdown::build_site()

# Preview locally
pkgdown::preview_site()